
Models
Models on the platform come from providers such as Qwen (Alibaba), Doubao (ByteDance), Kimi (Moonshot), MiniMax, GLM (Zhipu), DeepSeek, and Kling (Kuaishou), covering six capability categories.
The model list is updated daily: which models exist and what they cost is always governed by the console's Model Plaza in real time. This page doesn't enumerate the list — it explains three things: how models are categorized, how pricing works, and how to read model names.
Model Categories
How to call each category, with code examples, is in API Calls.
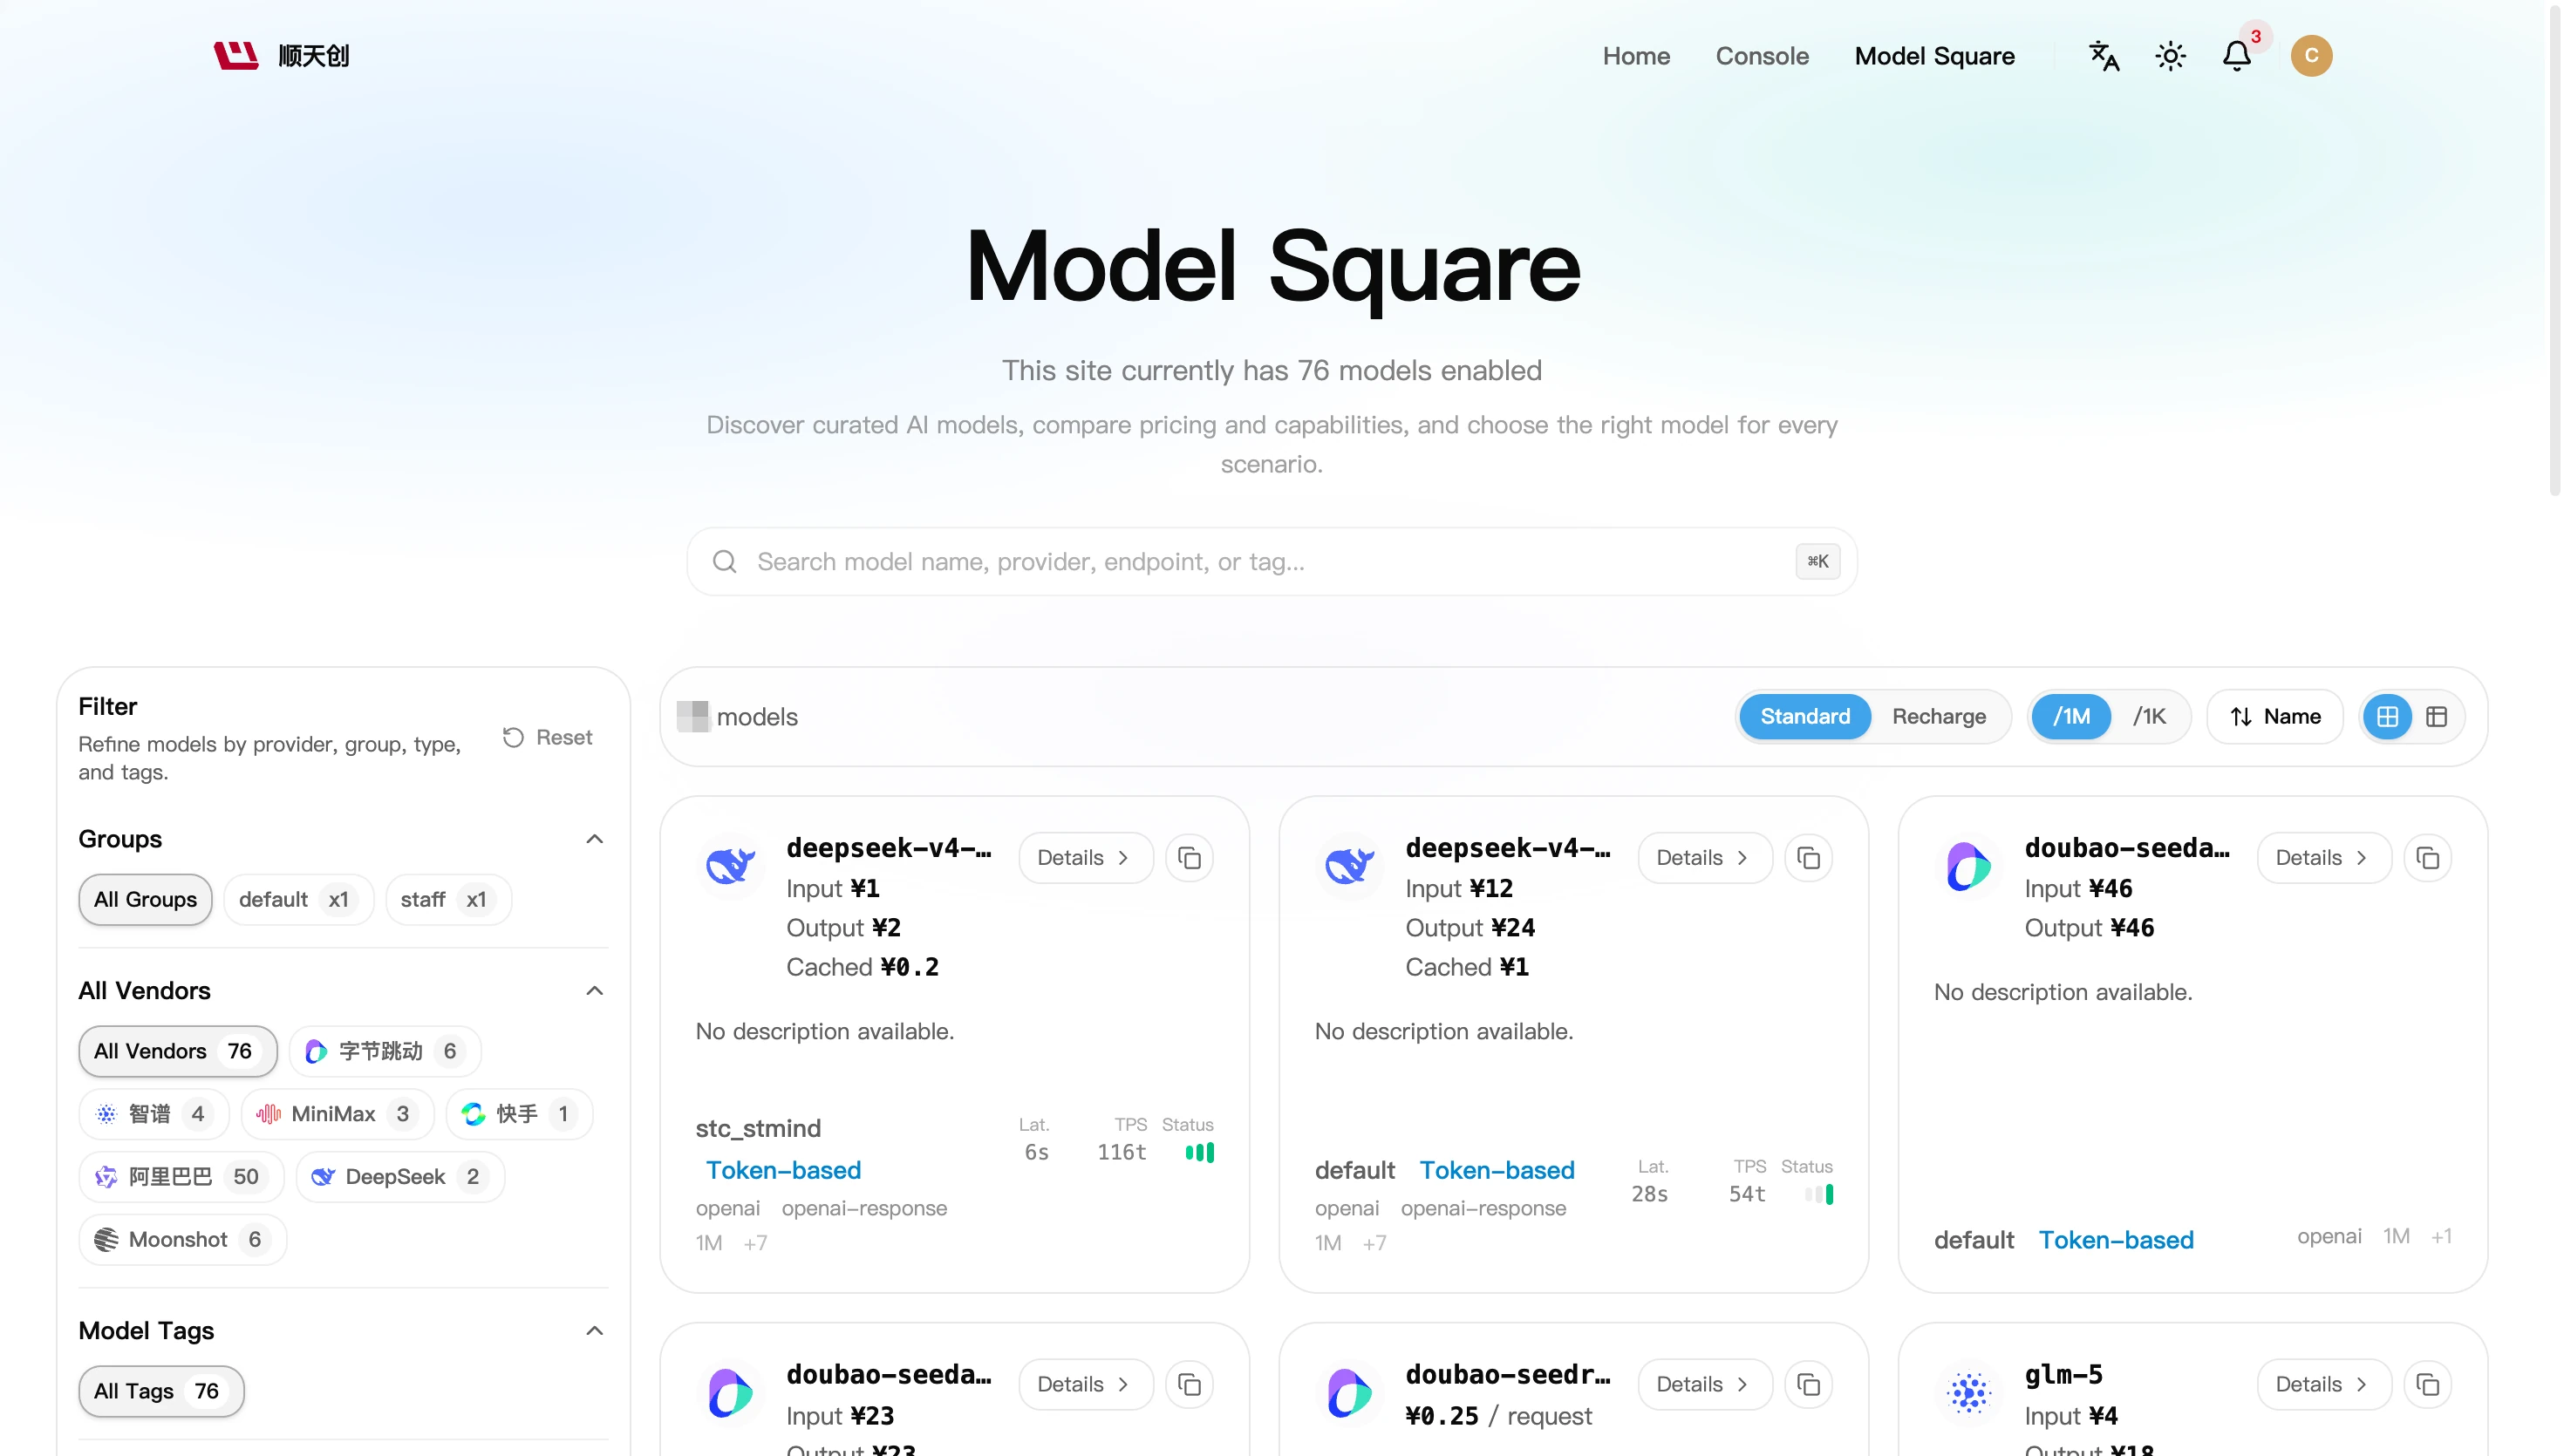
Finding Models and Prices in Model Plaza
Model Plaza (console → Model Plaza) is the single authoritative source of model information:
- Filter: combine filters by provider, group, pricing type, and endpoint type
- Search: search model names directly by keyword
- Copy name: click "Copy" on a model card to get the exact name to put in the
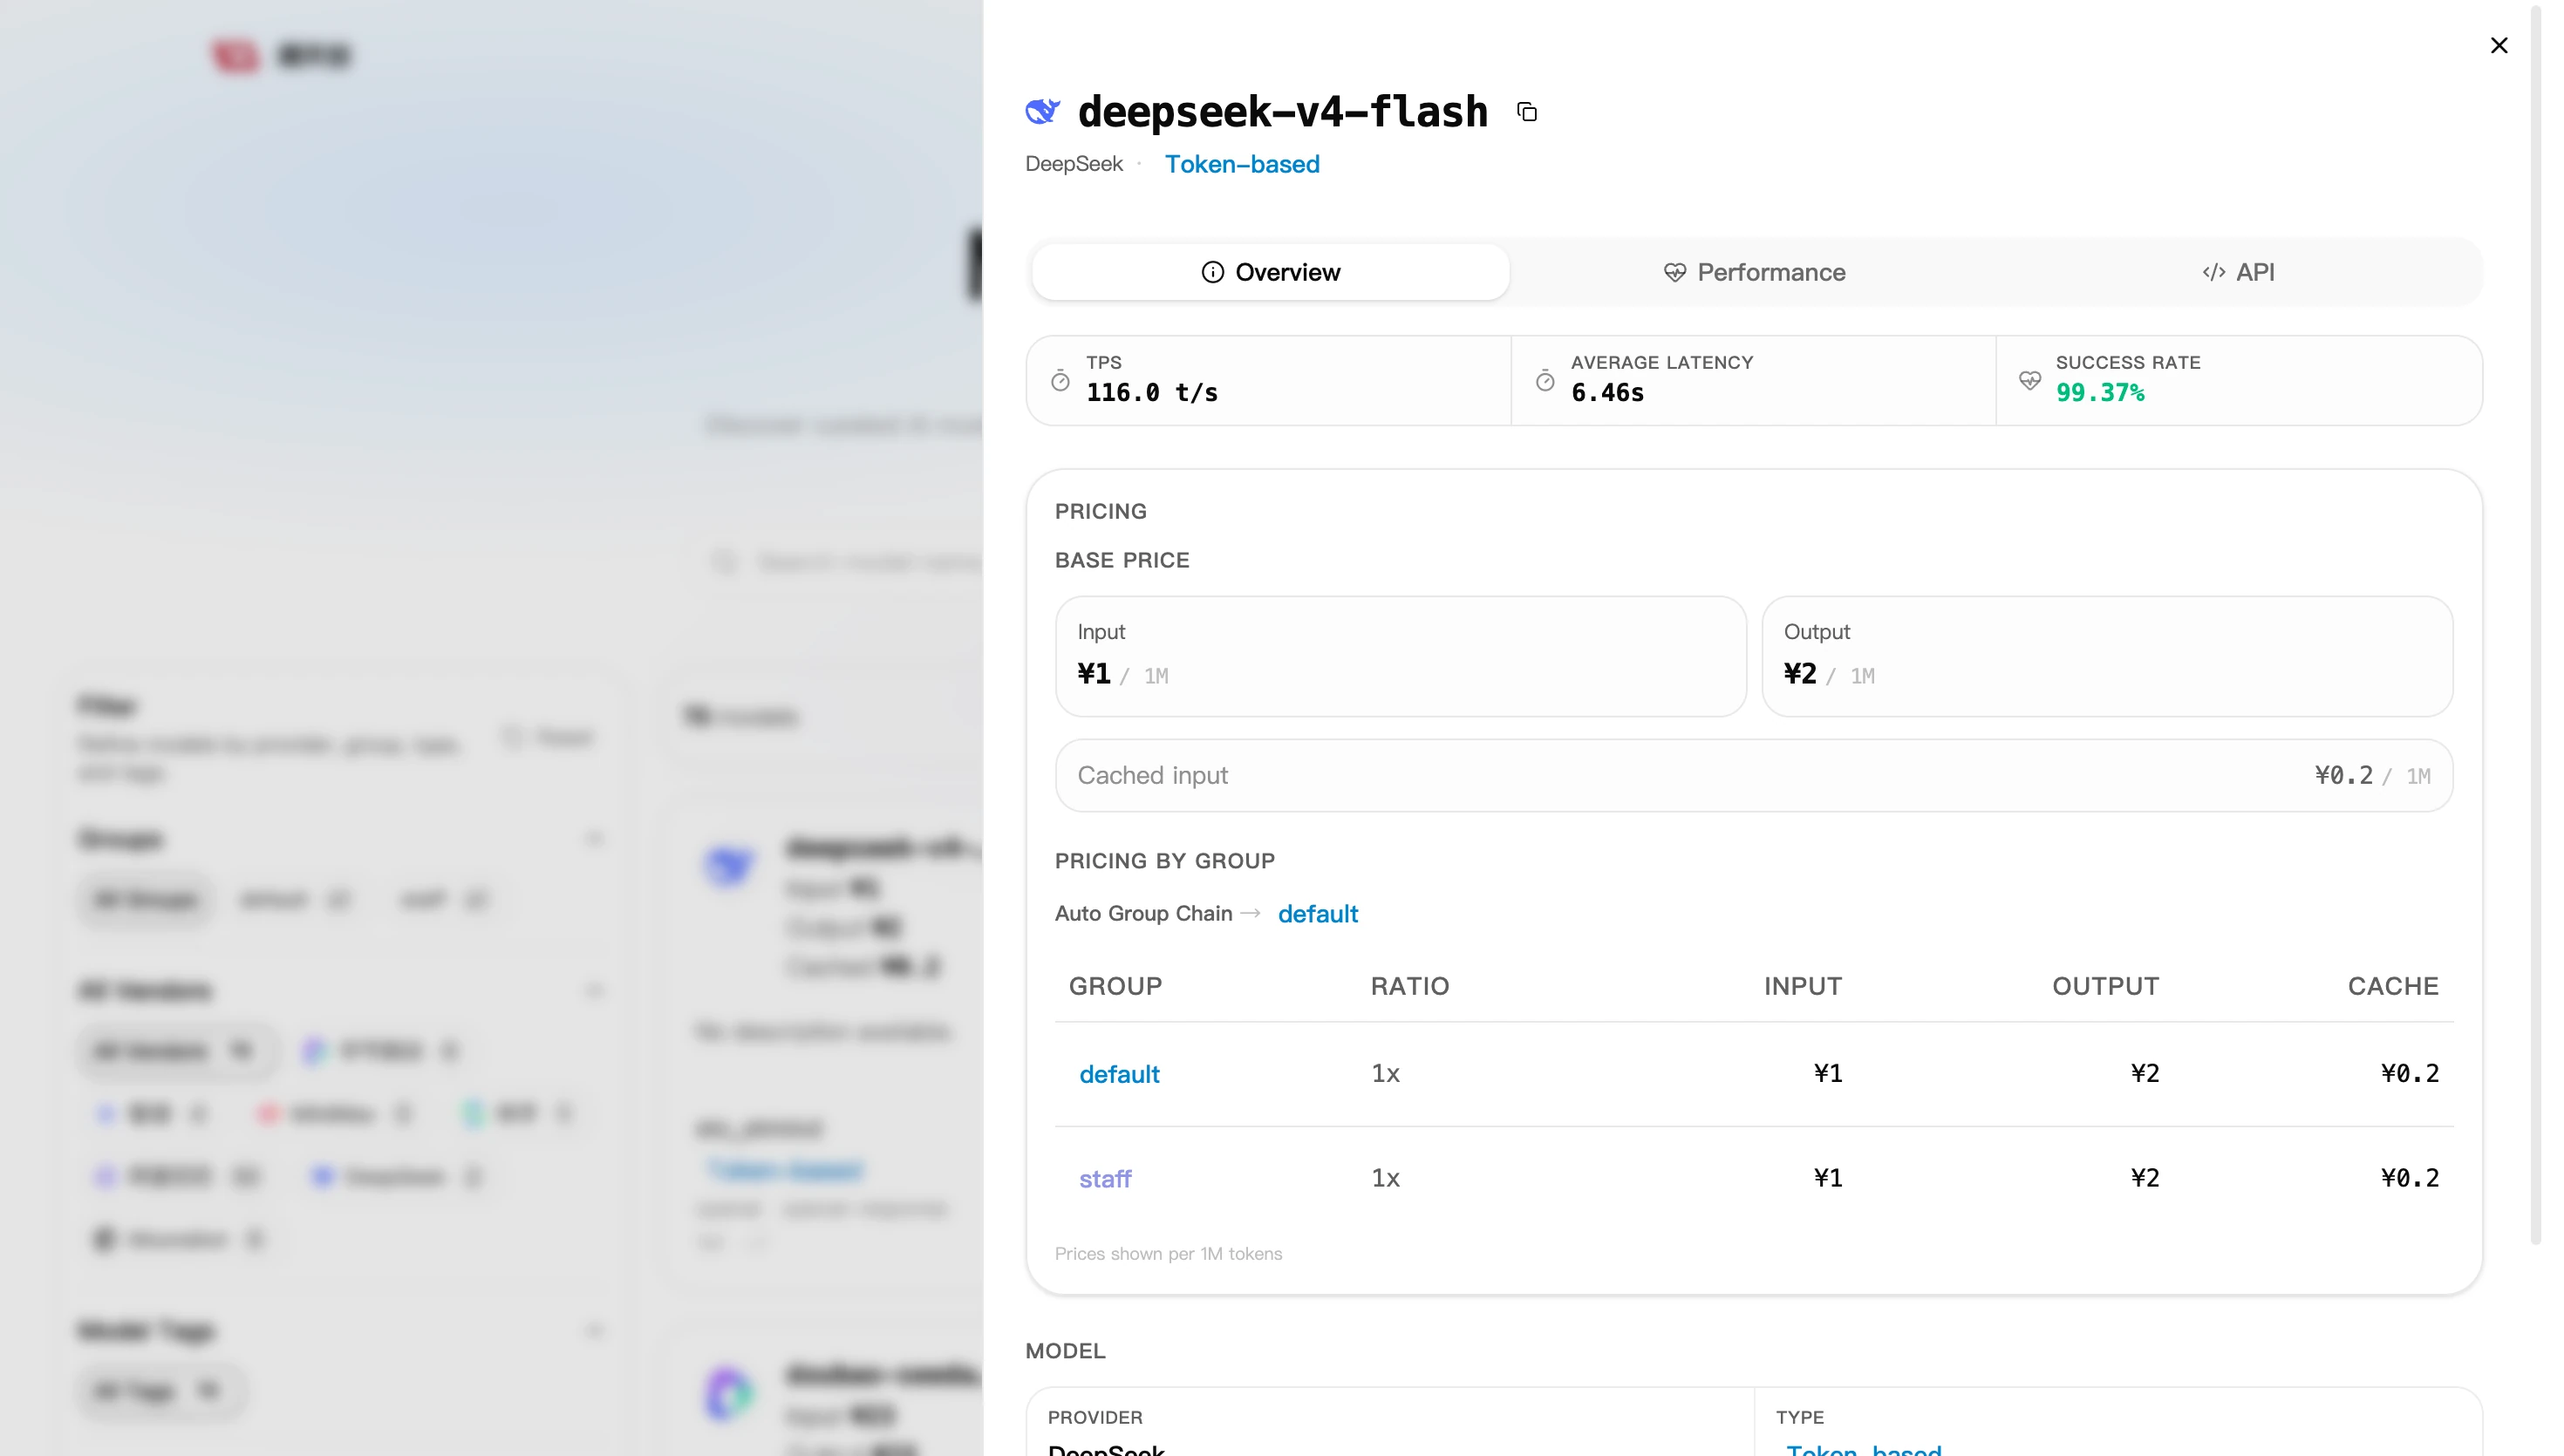
modelparameter - Check price: unit prices are shown right on the cards — ¥/million tokens for pay-as-you-go models, ¥/request for per-request models, and each tier's input-length range with its unit price for dynamic-billing models
- Details: click "Details" on a model card for the full information of that
model
Billing Methods
Charging rules and quota conversion (500,000 quota = ¥1) are in Billing & Top-up.
Groups
When creating an API Key you can pick a group (default / staff); a token can only use models in its group. Filter by group in Model Plaza to see each group's currently available models.
Model Naming Conventions
Name prefixes map to providers:
Common suffixes indicate a model's positioning:
Model names are case-sensitive: names differing only in case may be two different models with different prices (e.g. qwen-plus vs. Qwen-plus). Always copy the exact name from Model Plaza before calling.
Multi-Protocol Endpoints
Some chat models simultaneously support OpenAI Chat, OpenAI Responses, Anthropic (/v1/messages), and native Gemini endpoints. Filter by endpoint type in Model Plaza to find the models that currently support multiple protocols; how to connect to each endpoint is in Base URLs & Auth.
Choosing a Model
Match your need to a suffix (meanings in "Model Naming Conventions" above):
Not sure which to pick? Try them side by side in the console Playground, or start with the cheapest flash series and step up if the quality isn't enough.